
Watch a busy routing page for a week and one column does the arguing for you: the token volume that real requests pile onto each row. On the OrcaRouter comparison page we publish that raw evidence — every model’s seven-day token volume sits next to its price and its latency, so a llm comparison reads like a market report instead of a wish list.
The seven-day volume column is the closest thing we publish to a real-world vote — hundreds of millions of tokens, all routed by people with working budgets.
The busiest rows in the table
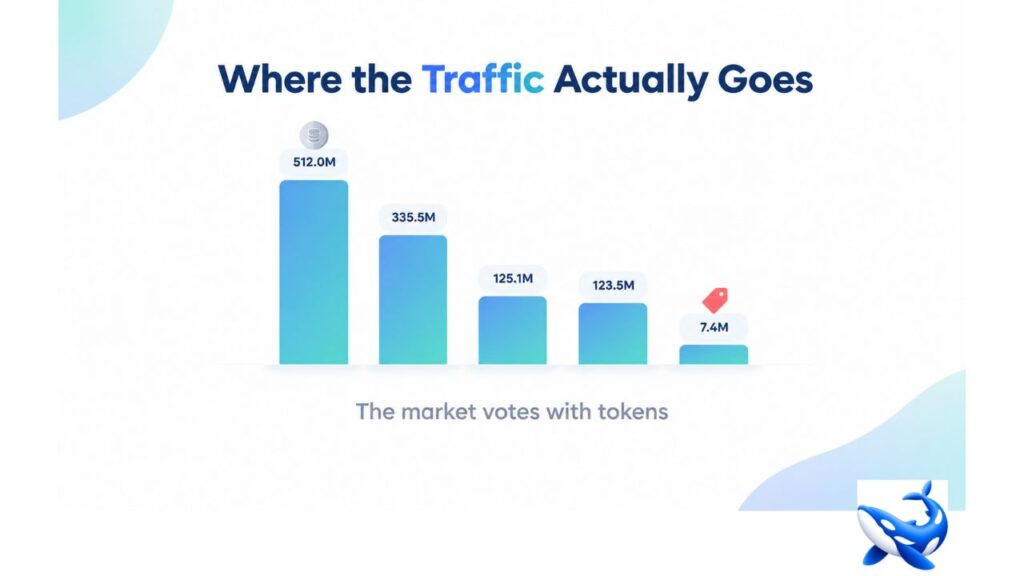
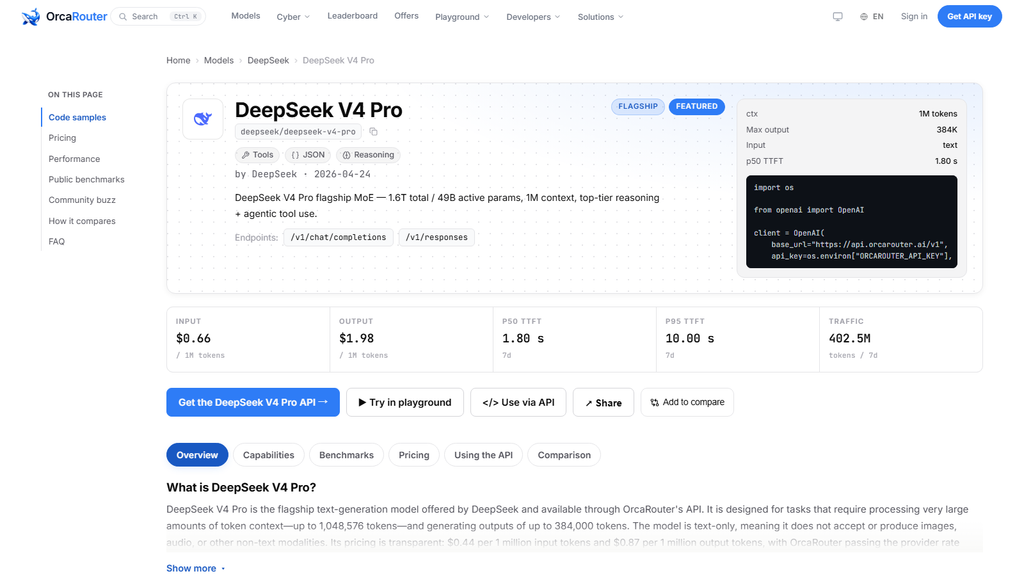
The leader is DeepSeek V4 Pro, and it is not a close race. Over the trailing seven days it handled 512.0 million tokens of production traffic on our side, at $0.66 per million input tokens and $1.98 per million output. That is a quality score of 8 out of 10 on our own composite — a number we build ourselves, grading each model on our own quality dimensions, not a third-party benchmark — and it is the cheapest full-sized row in the table by a wide margin.
Second place is Gemini 3.8 Flash at 335.5 million tokens, $0.75 per million input and $3.75 per million output. Then the field spreads out: GPT-6 Sol at 125.1 million tokens, $2.00 per million input and $10 per million output, and Claude Opus 5.5 close behind at 123.5 million tokens with a $4.00 input and a $20.00 output price. Below them the numbers fall off a cliff. Claude Sonnet 5.5 at 48.8 million, Gemini 3.1 Pro Preview at 42.8 million, kimi-k2.6 at 34.9 million, Grok 4.7 at 27.1 million, GPT-5.4 at 6.8 million, and the two most expensive rows barely register: Claude Fable 5.1 at 7.4 million and GPT-5.5 Pro at 101.8 thousand. Read the column top to bottom once and the shape is unmistakable, and it is a shape that repeats in week after week of the same data.
What the column does and does not mean
Read carefully, and the pattern is obvious: money flows to cheap. The two rows priced at $0.66 and $0.75 per million input tokens are also the two busiest rows by token volume, and between them they carry nearly 850 million tokens of a weekly total that the entire rest of the table adds up to about half that. Nobody is forcing this outcome and no marketing campaign arranged it. It is the aggregate of thousands of production decisions made by people who compare the same columns you are comparing right now.
The column has a boundary and it should stay one. Volume measures requests, not quality — a model can be heavily used because it is cheap, because it is the default in a popular tool, or because it is genuinely good at a niche job, and the column cannot separate those causes. It is a market vote, not a scoreboard, which is why it sits next to, not on top of, the quality column. That is also why we label it as seven-day volume in our own composite — a rolling window that changes every day, exactly like the latency numbers beside it.
The quiet rows are not failures
The expensive rows are the interesting part of the story, because the market’s silence there is information. Claude Fable 5.1 costs $10 per million input tokens and $50 per million output — the dearest of the three leading-vendor cards — and it carries only 7.4 million tokens of seven-day volume, about one-seventieth of what the cheapest row does. GPT-5.5 Pro is an even sharper case: at $30 per million input tokens and $180 per million output it is the most expensive model in the table, its context window is not published, and its seven-day volume of 101.8 thousand tokens is four orders of magnitude smaller than the busiest row.
None of that makes the premium rows bad. A model can be rarely run and still be the right choice for the narrow, high-value jobs where price barely matters. But it does tell you something a score alone cannot: at these prices, almost nobody is running these models at scale. When a team’s traffic is your evidence, the absence of traffic is evidence too.
The counter-example that keeps it honest
The story would be too tidy if price alone explained everything, and one row breaks the pattern. MiniMax M2.7 highspeed is the cheapest model in the entire table — $0.60 per million input tokens and $2.40 per million output — yet its seven-day volume is just 3.2 thousand tokens, essentially zero compared with the leaders. If cheap always won, this row would be the busiest one of all.
What that teaches is that price is a necessary condition for volume, not a sufficient one. Teams adopt a model when it is cheap enough to run at scale, yes, but also when it is available, known, and proven in the workloads they care about. MiniMax M2.7 highspeed is a specialty row — a fast, small card whose 3.29-second p50 time-to-first-token is genuinely quick — but being cheap and fast is not the same as being on every engineering shortlist. The market votes with tokens, but it votes after it has heard of you. A row can also be quiet because it is new, or because its vendor has not shipped the integrations the rest of the ecosystem takes for granted, and a single week of volume will not tell you which of those it is.
What this means for your stack
The practical takeaway is a question you can ask before you spend anything: does my workload resemble the traffic in the volume column, and should it? For most teams the honest answer is that their traffic looks nothing like the premium rows. If you are shipping a production feature that handles ordinary requests, the 512.0 million-token row at $0.66 per million input is the market’s answer to what works at scale, and the 101.8 thousand-token row at $30 per million input is the market’s answer to what most teams cannot afford to run.
Price your next project against the volume column, not the score column. Pick the cheapest row that passes your quality bar, keep the expensive rows for the narrow jobs where they genuinely pay for themselves, and re-read the column next week — the window rolls daily, and the market’s vote changes with it.
The takeaway
The market puts its money where the price is. DeepSeek V4 Pro at $0.66 per million input tokens carried 512.0 million tokens of seven-day traffic on our side, Gemini 3.8 Flash at $0.75 carried 335.5 million, and the two most expensive rows in the table — Claude Fable 5.1 at $10 and $50, and GPT-5.5 Pro at $30 and $180 — carried 7.4 million and 101.8 thousand respectively. Volume is a vote, not a verdict, but it is the only vote cast with real budgets.
Let the volume column test your assumptions about which models are worth running. If the busiest row is also the cheapest row that meets your bar, the market already did the diligence for you — and the scoreboard was never the whole story anyway.
Sourcing note: all prices, context windows, p50 time-to-first-token figures, seven-day token volumes and composite quality scores are OrcaRouter production data from the comparison page and the linked model page, read 2026-10-12. The volume and latency figures are rolling telemetry that will drift. All checked 2026-10-12